HPC Cluster Support & Administration.
HPC Cluster Troubleshooting, Linux Compute Nodes, Slurm/PBS Scheduling, GPU Computing, MPI, Storage, Networking and Cluster Maintenance.
Review the scope against your environment.
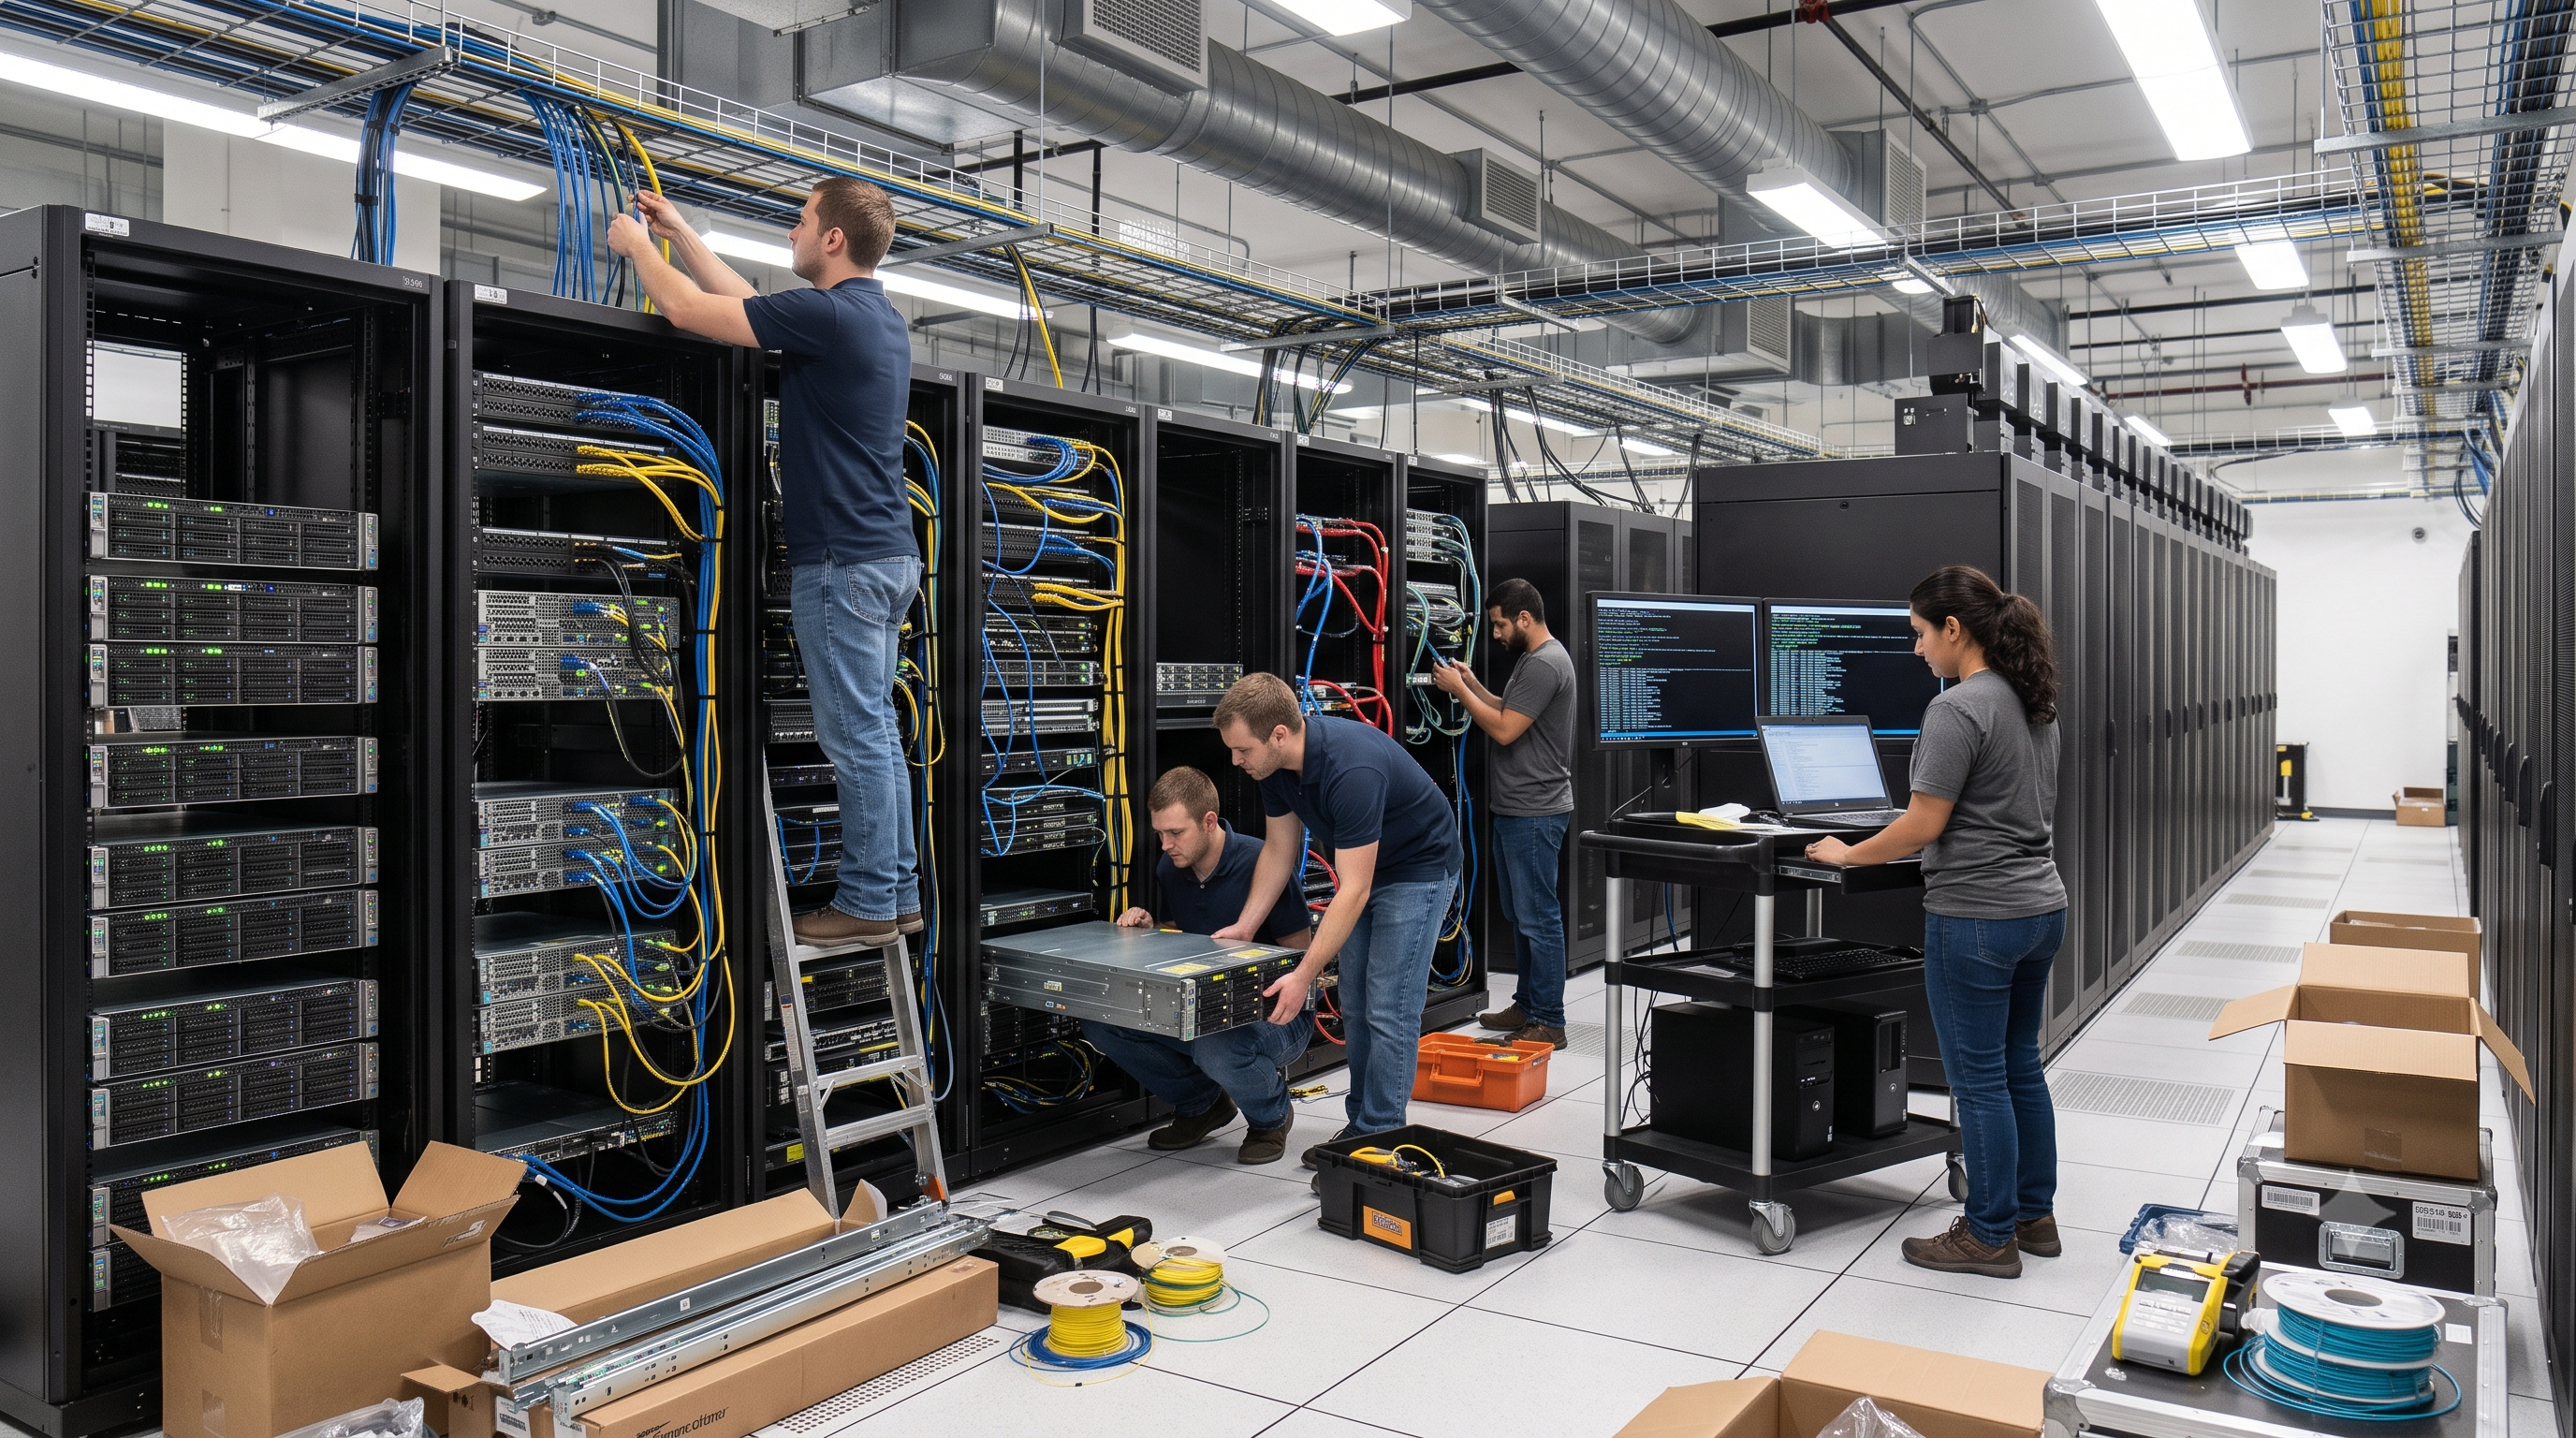
MCR Tech provides HPC Cluster Support and Administration services to research laboratories, universities, engineering organizations, AI teams and enterprises operating High Performance Computing infrastructure. We help maintain and troubleshoot existing HPC clusters, compute nodes, job schedulers, GPU environments, storage systems and high-speed networks. Our support services are designed to improve cluster reliability, identify operational issues and help administrators manage computing resources efficiently. **Our HPC Cluster Support Services Include:** 1. HPC Cluster Health Checks: Review node availability, system resources, service status, logs and cluster health. 2. Linux Compute Node Support: Troubleshoot Linux operating systems, package dependencies, system services, SSH access and compute node configuration. 3. Slurm Workload Manager Support: Diagnose job submission errors, queue problems, pending jobs, node states, partitions and resource allocation issues. 4. PBS Scheduler Support: Troubleshoot job queues, scheduling policies, compute resources and job execution problems in supported PBS environments. 5. CPU and GPU Troubleshooting: Investigate CPU utilization, GPU availability, driver issues, memory errors and workload performance problems. 6. MPI and Parallel Computing Support: Assist with MPI configuration, multi-node communication, library dependencies and parallel job execution. 7. Cluster Networking Support: Troubleshoot node connectivity, DNS, IP configuration, Ethernet, InfiniBand and communication issues. 8. Shared Storage Support: Diagnose NFS, NAS, SAN and supported parallel storage access, permissions, capacity and performance problems. 9. Software and Application Support: Assist with scientific applications, compiler environments, software dependencies, environment modules and workload-specific configuration. 10. Performance Monitoring and Optimization: Review CPU, GPU, memory, storage, network and scheduler metrics to identify possible bottlenecks. 11. Cluster Updates and Maintenance: Assist with operating system updates, package maintenance, configuration checks and planned maintenance activities. 12. User and Access Management: Support user accounts, group permissions, SSH keys, storage quotas and controlled access to computing resources. 13. Cluster Troubleshooting and Recovery: Investigate failed jobs, unavailable nodes, service interruptions, configuration errors and recurring system issues. 14. Monitoring and Documentation: Help configure monitoring, maintain troubleshooting records and document cluster operating procedures. 15. Remote Technical Support: Provide remote troubleshooting and administration assistance when authorized access and suitable connectivity are available. **Who Can Benefit?** HPC administrators, research laboratories, universities, AI and machine learning teams, scientific computing groups, engineering companies and organizations running multi-node compute infrastructure. **Why Choose MCR Tech?** MCR Tech focuses on Linux administration, HPC operations, job scheduling, GPU computing, storage, networking and infrastructure troubleshooting. Support activities are planned according to the existing cluster architecture, workload requirements and agreed scope of service. For HPC cluster troubleshooting, scheduler support, Linux compute node administration or infrastructure maintenance, contact support@mcrtech.co.in. Website: https://mcrtech.co.in
Work included, supported versions, access requirements, timing, commercial terms, validation and handover are agreed for each request. A service listing is not a guaranteed product compatibility or response-time commitment.
Technologies referenced in this service
What this service includes
- HPC Cluster Health Checks
- Linux Compute Node Troubleshooting
- Head Node and Login Node Support
- Slurm Installation and Troubleshooting
- PBS Scheduler Configuration and Support
- Job Queue and Scheduling Issues
- CPU and GPU Compute Troubleshooting
- NVIDIA GPU Driver and CUDA Issues
- MPI and Multi-Node Communication
- Ethernet and InfiniBand Networking
- NFS and Shared Storage Troubleshooting
- Parallel Filesystem Support
- Scientific Application Configuration
- Compiler and Software Dependency Management
- Environment Modules Configuration
- Node Availability and Resource Monitoring
- User Accounts and Access Permissions
- Cluster Performance Analysis
- Operating System Updates and Maintenance
- Remote HPC Technical Support
Potential use cases listed for this service
- Reduce downtime in HPC computing environments
- Identify compute node failures and configuration issues
- Troubleshoot pending and failed scheduler jobs
- Improve CPU and GPU resource utilization
- Resolve MPI and multi-node communication problems
- Maintain reliable shared storage access
- Identify network and storage performance bottlenecks
- Improve cluster monitoring and operational visibility
- Maintain consistent software environments across nodes
- Support research and scientific computing workloads
- Improve system maintenance and troubleshooting processes
- Help administrators manage cluster resources efficiently
- Support AI and GPU computing infrastructure
- Maintain cluster configuration and operational documentation
- Extend the useful life of existing computing infrastructure
Related: reference architectures, HPC & AI applications, and cluster planning.