HPC & AI Cluster Deployment Services.
Professional HPC cluster deployment, AI and GPU cluster setup, Linux server configuration, high-performance networking, shared storage, Slurm scheduling and scientific computing infrastructure for research labs, universities and enterprises.
Review the scope against your environment.
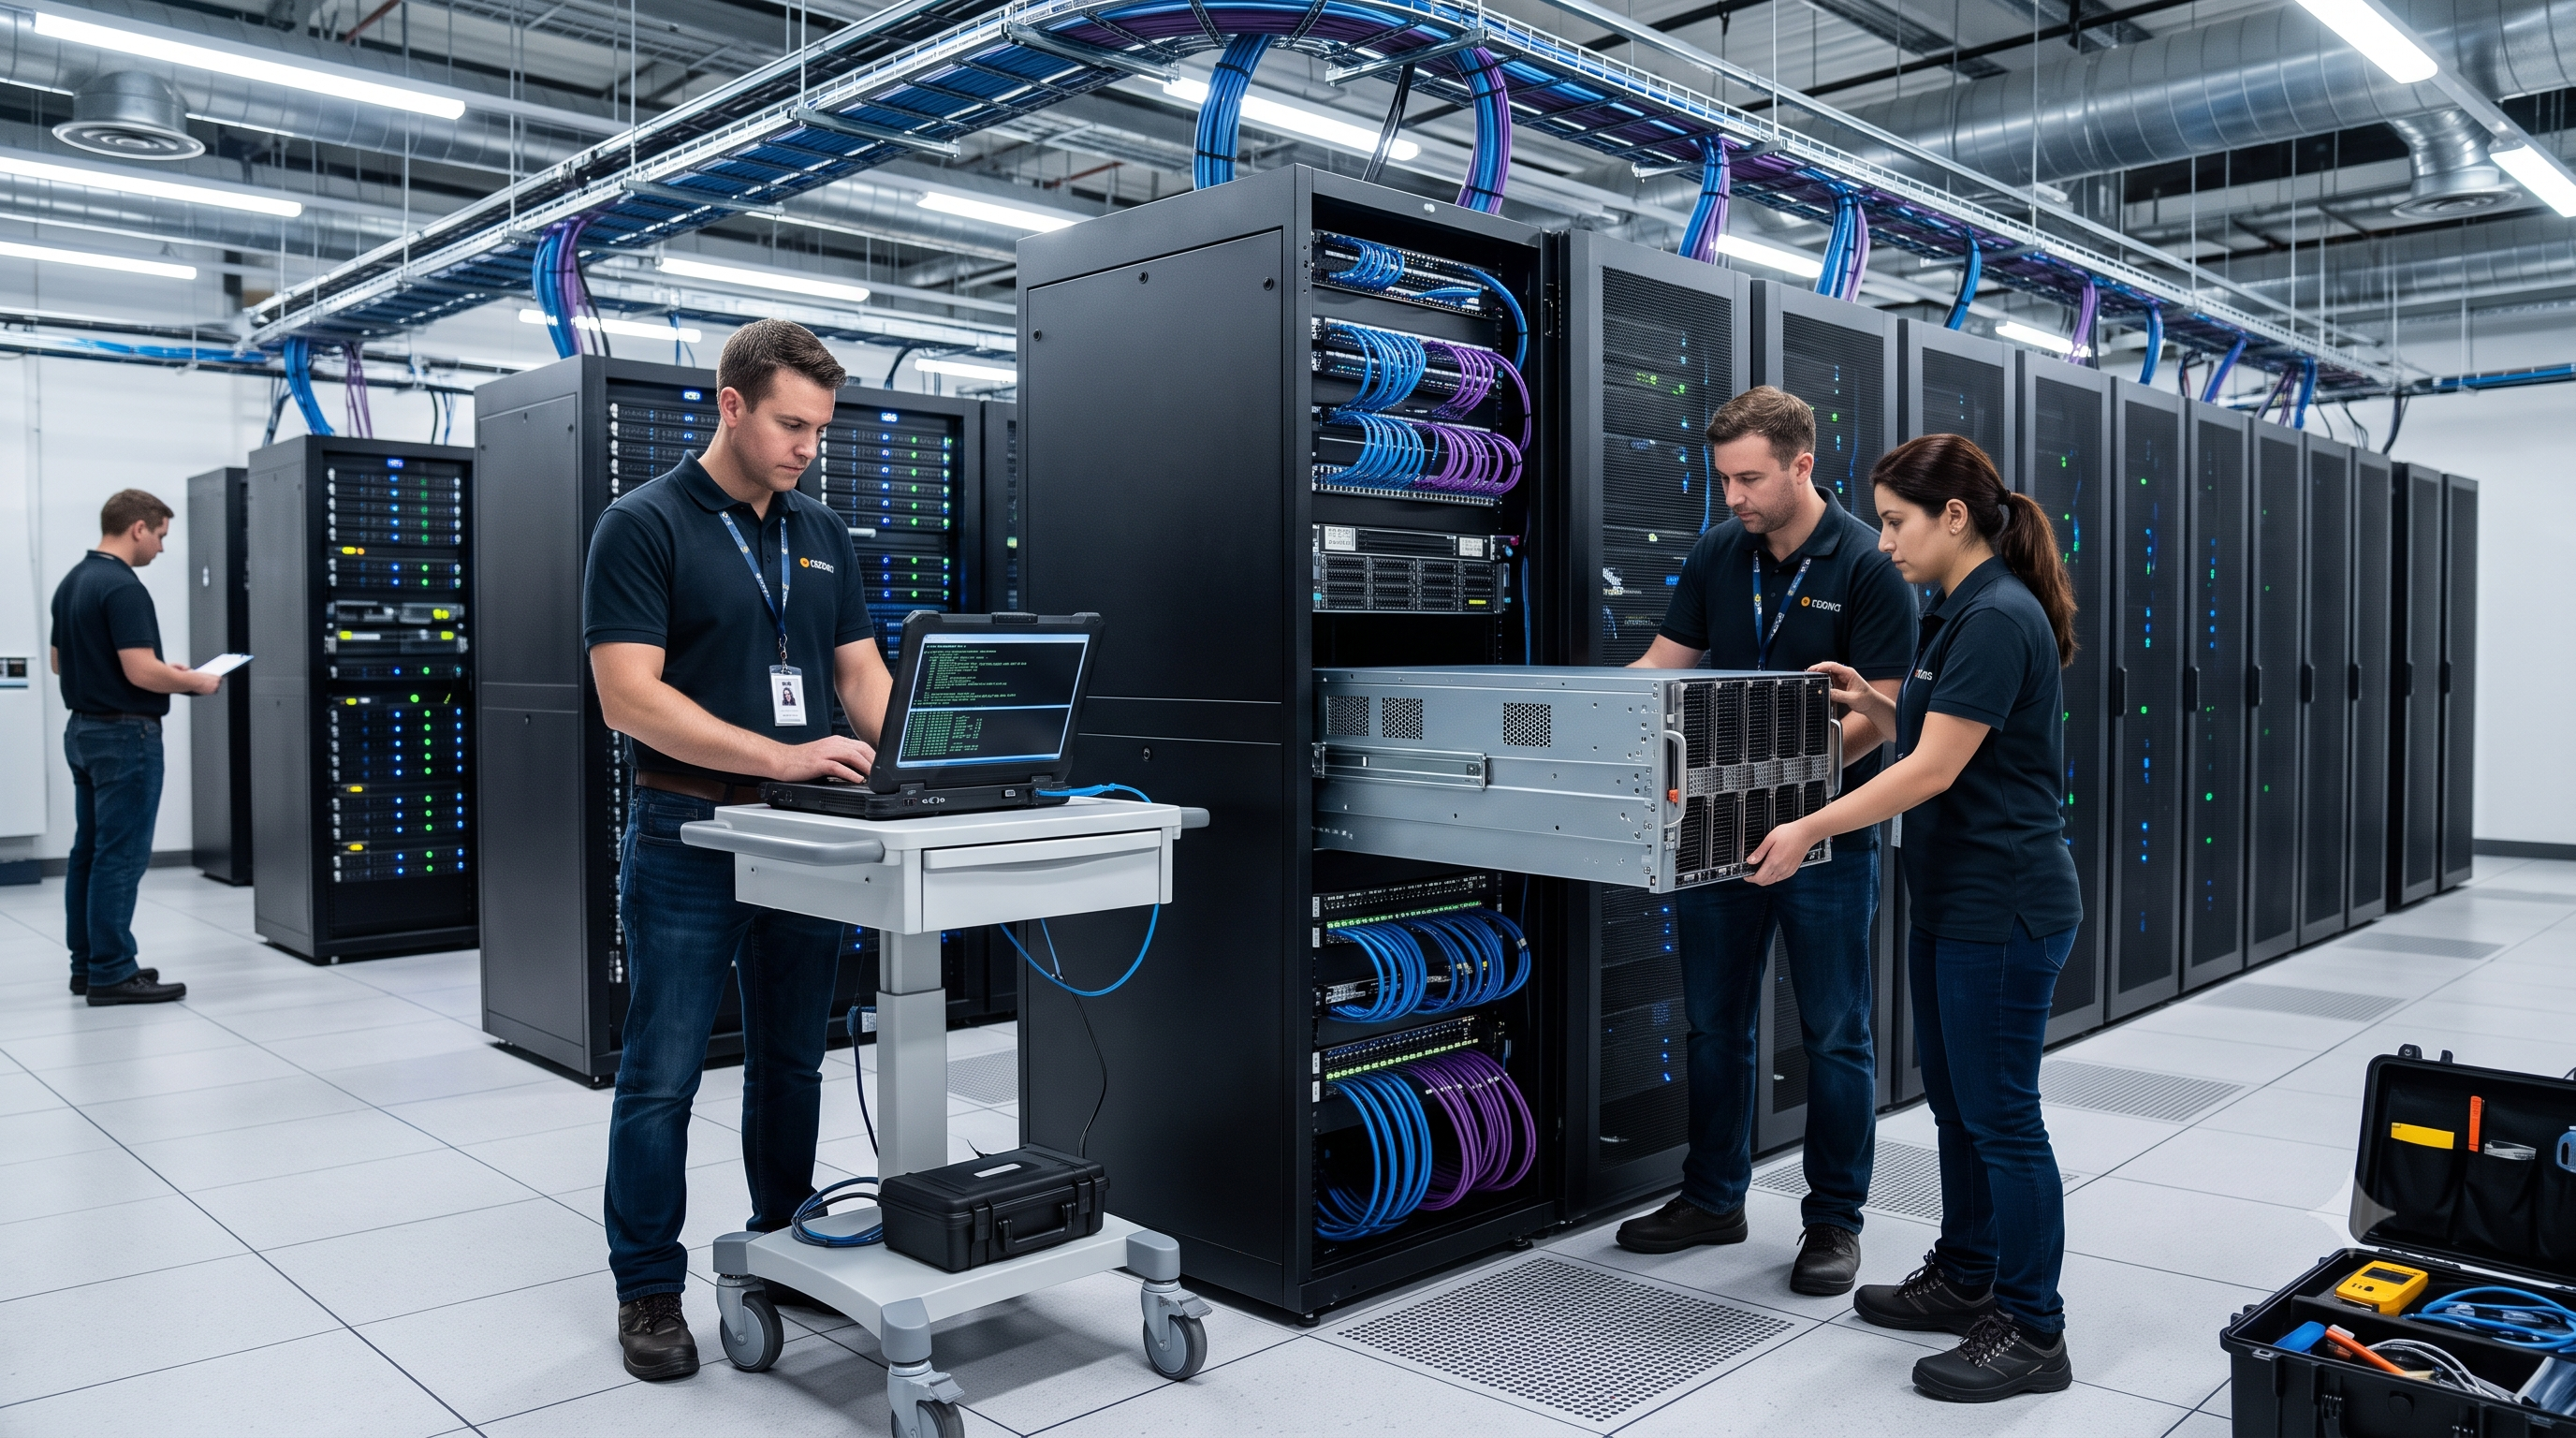
# HPC & AI Cluster Deployment Services MCR Tech provides HPC cluster deployment and AI computing infrastructure setup services for research laboratories, universities, engineering teams, enterprises and datacenters. ## High Performance Computing (HPC) Cluster Setup Build a computing cluster designed for parallel processing, scientific simulations, engineering workloads and research computing. Our deployment approach covers cluster architecture planning, head node and compute node configuration, Linux installation, network connectivity, shared storage integration and workload scheduling. ## AI and GPU Cluster Deployment Prepare infrastructure for artificial intelligence, machine learning, deep learning and GPU-accelerated computing. Depending on project requirements, the architecture may include GPU servers, CPU compute nodes, Linux-based systems, GPU software environments and high-speed networking. ## Linux Cluster Installation and Configuration Configure Linux servers and cluster nodes with suitable operating systems, hostname and network settings, SSH access, user accounts, software dependencies and administrative tools. Deployment is planned around the hardware, applications and operational requirements of each customer. ## HPC Scheduler and Parallel Computing Setup Set up and configure workload scheduling solutions such as Slurm or supported PBS implementations. Where required, prepare MPI environments and test communication between nodes for distributed and parallel applications. ## Cluster Networking and Shared Storage Integrate Ethernet or InfiniBand networking where supported by the selected hardware. Configure appropriate shared storage solutions, node connectivity and access permissions to support application data, research workloads and collaborative computing. ## Cluster Testing, Documentation and Handover Validate node connectivity, system health, scheduler operation and selected workloads. Provide deployment documentation and administrator guidance according to the agreed project scope. ## Who Can Benefit? Our HPC and AI cluster deployment services are relevant to research institutions, universities, scientific computing teams, engineering and simulation environments, AI development teams and organizations building on-premises computing infrastructure. Contact MCR Tech to discuss your server hardware, CPU/GPU requirements, number of nodes, networking, storage and application workloads. Email: support@mcrtech.co.in
Work included, supported versions, access requirements, timing, commercial terms, validation and handover are agreed for each request. A service listing is not a guaranteed product compatibility or response-time commitment.
Technologies referenced in this service
What this service includes
- HPC Cluster Deployment and Installation
- AI and GPU Cluster Setup
- High Performance Computing Infrastructure
- Linux Server Installation and Configuration
- Head Node and Compute Node Setup
- CPU and GPU Compute Node Configuration
- HPC Cluster Architecture and Planning
- High-Speed Ethernet and InfiniBand Networking
- Shared Storage and Cluster Filesystem Integration
- Slurm Workload Manager Installation and Configuration
- PBS Workload Scheduler Setup
- MPI and Parallel Computing Environment
- AI Model Training Infrastructure Setup
- Scientific Computing and Simulation Environments
- Cluster Monitoring and Performance Testing
- Cluster Troubleshooting and Optimization
- User Management and Secure SSH Access
- Cluster Documentation and Administrator Training
Potential use cases listed for this service
- HPC Cluster Setup for Research Laboratories and Universities
- AI and GPU Computing Infrastructure for Machine Learning
- High Performance Computing for Scientific Research
- Parallel Processing for Engineering and Scientific Simulations
- Scalable Computing Infrastructure for Growing Workloads
- Centralized Management of Compute Nodes and User Accounts
- Improved Compute Resource Utilization and Workload Scheduling
- AI Model Training and Deep Learning Workloads
- Research Computing for Universities and Institutions
- Linux-Based HPC Cluster Deployment for Enterprises
- GPU Server Integration for AI Workloads
- Reliable Cluster Connectivity and Shared Data Access
- Infrastructure Planning for New HPC and AI Labs
- Cluster Performance Validation and Operational Readiness
- Custom HPC Infrastructure Based on Workload Requirements
Related: reference architectures, HPC & AI applications, and cluster planning.